Serverless platforms bill per second of inference, but loading a large model before the first token can take tens of seconds. This project follows that cold start end to end. It starts on a laptop, taking a 2 GiB checkpoint apart and measuring every stage until a loader-friendly checkpoint format logically follows from profile measurements in a bottom-up approach. Then it walks through ServerlessLLM (OSDI ‘24), which I co-authored: using the idle storage inside GPU servers as a checkpoint cache, live-migrating inference by moving tokens instead of gigabytes and scheduling for startup time. It ends with where this goes next, from agents where every step is a cold start to RL fine-tuning, where generation dominates the cost.
Serverless LLM Inference
Dec 20251 The Anatomy of an LLM Cold Start Taking a 2 GiB checkpoint apart on a laptop and timing every stage until a loader-friendly format logically follows from profling measurements in a bottom-up approach.
3 posts
-
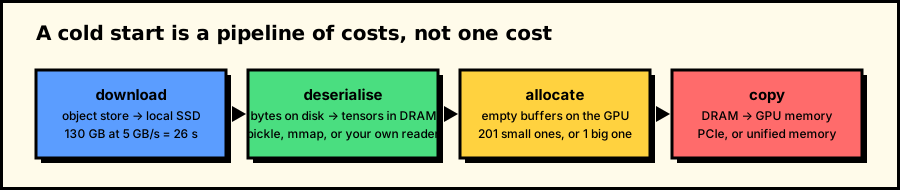
Anatomy of an LLM Cold Start, Part 1: Where the Time Goes
Serverless platforms bill per second of inference, but a model can take many seconds to load before the first token appears. In this post I take a 2 GiB checkpoint apart on a laptop and measure where that time goes.
Read -
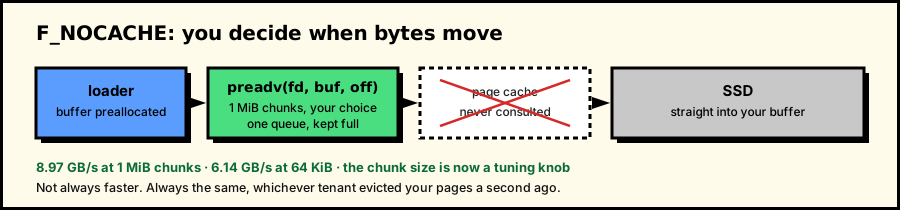
Anatomy of an LLM Cold Start, Part 2: Make It Predictable, Then Make It Fast
safetensors reports a 2 ms load that is physically impossible, because mmap defers the real cost to page faults and the page cache makes measurements hard to trust. This post bypasses the page cache and then overlaps the read with the copy.
Read -
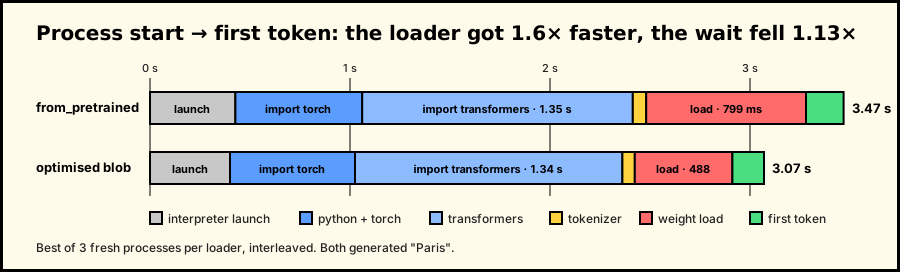
Anatomy of an LLM Cold Start, Part 3: A Checkpoint Format Written for the Reader
Every optimisation so far made the reader work around a file layout it did not choose. Moving that work to the write side, which happens once, leaves the loader with nothing to do but move bytes. The end-to-end measurement then shows that loading is no longer the largest cost of a cold start.
Read
2 ServerlessLLM Paper Breakdown: Key Design Contributions The OSDI '24 paper, one contribution per post. Checkpoint caching on idle server storage, live migration of tokens and startup-time-aware scheduling.
3 posts
-
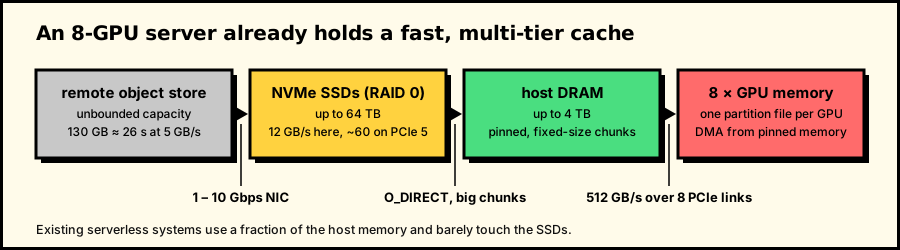
ServerlessLLM Paper Breakdown, Part 1: Your GPU Server Is Also a Storage Server
Why serverless LLM inference has cold starts of tens of seconds, why the usual fixes do not scale to 100 GB checkpoints and the observation behind our OSDI'24 paper: an 8-GPU server already contains terabytes of fast storage that sits mostly idle.
Read -
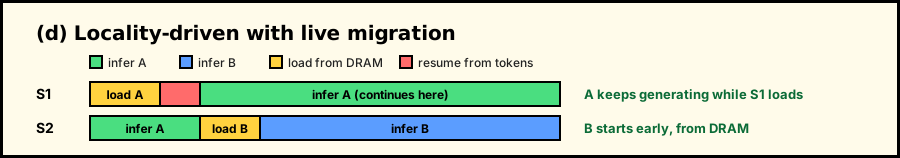
ServerlessLLM Paper Breakdown, Part 2: Migrate Tokens, Not Gigabytes
Locality only helps if requests go where the weights are and that GPU is often busy. Live migration of a running LLM inference sounds expensive, but it is cheap if you move a few kilobytes of tokens and recompute the KV cache, which is about ten times faster than generating the tokens.
Read -
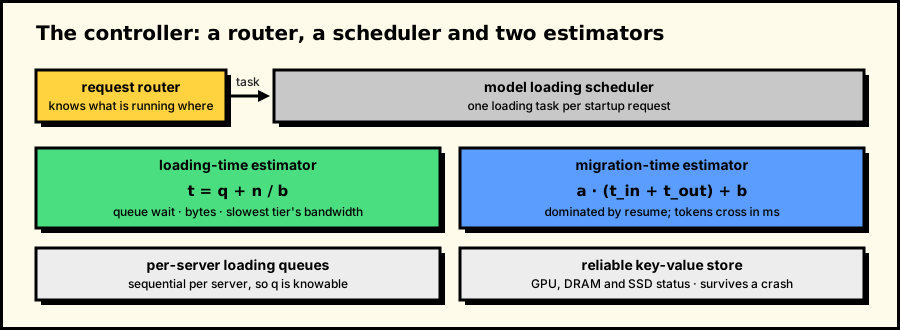
ServerlessLLM Paper Breakdown, Part 3: Scheduling for Startup Time
A scheduler that estimates how long every server would take to start a model, from its queue, the model size and the slowest storage tier involved, then picks the cheapest. It also covers the end-to-end comparison with KServe and Ray Serve and my advice for practitioners.
Read
3 Token Factories: A Design Proposal for Serverless LLM Agents Where this goes next. Agents where every step is a cold start and RL fine-tuning, where generation dominates the cost.
2 posts
-
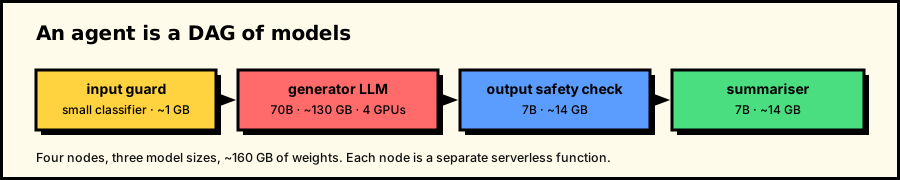
Serverless Agents: When Every Step Is a Cold Start
An agent is usually a DAG of models, hundreds of gigabytes in total and today it is often built as hand-written microservices connected with Kafka. I argue that serverless suits these workloads, but only with an LLM-aware storage and scheduling layer underneath and I describe the experiment I want to run to test this.
Read -
Why RL Needs Low-Latency Inference
Notes from adding PPO, online RL and GRPO to ServerlessLLM. In every design the main cost was generating text, not the gradient step.
Read